Silent Variables: The Hidden Reproducibility Problem Threatening Computational Biology
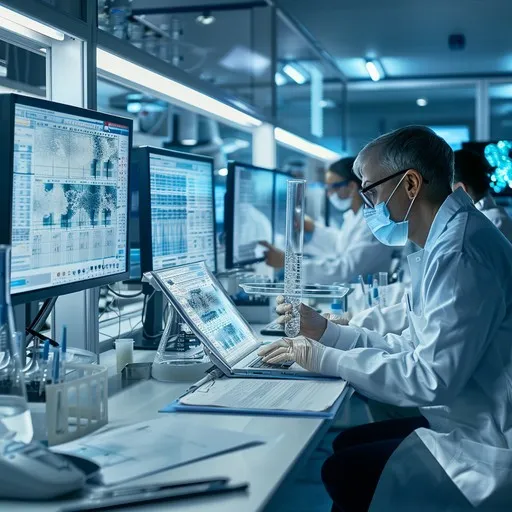
Photo: bioinformatics researcher analyzing genomic data on multiple computer screens in laboratory, via images.stockcake.com
For decades, computational approaches in biology carried an implicit promise: unlike bench experiments, which depend on the deft hands of individual researchers and the temperamental behavior of living cells, algorithms could be run again and again, yielding identical results. That promise has aged poorly. A quiet but consequential crisis has taken root in bioinformatics and computational biology, one in which the very tools designed to bring precision to biological inquiry are themselves producing findings that resist independent verification.
The problem is not always visible in published methods sections. It lives, instead, in the gap between what researchers describe and what their computational environments actually do.
The Illusion of Algorithmic Precision
When a molecular biology lab fails to reproduce a result, the community has well-worn explanations at hand: reagent quality, cell line contamination, operator variability. Computational failures are subtler and, in some respects, more insidious. A pipeline that runs without error is not necessarily a pipeline that runs correctly — or consistently across environments.
Software versioning is among the most pervasive sources of hidden variability. A bioinformatics workflow built around a specific release of a tool such as GATK, DESeq2, or Bowtie may produce meaningfully different outputs when executed under a subsequent version, even when the underlying algorithm has not been intentionally changed. Minor patches, revised default parameters, and updated dependency libraries can all shift numerical results in ways that are difficult to detect without direct comparison. In a 2019 analysis published in PLOS Computational Biology, researchers demonstrated that variant-calling pipelines applied to identical genomic datasets produced substantially divergent variant lists depending solely on software version — differences with direct implications for downstream clinical interpretation.
Hardware architecture introduces a second, less frequently discussed layer of variability. Floating-point arithmetic, the mathematical foundation of most numerical computation, does not behave identically across processor architectures or even across compiler optimization settings on equivalent hardware. For iterative algorithms that accumulate small numerical differences across thousands of steps, these discrepancies can compound into results that are statistically and biologically distinct from those generated on a different machine.
Undocumented Parameters and the Phantom Methods Section
Perhaps the most consequential reproducibility barrier, however, is one that researchers impose on their own work without necessarily intending to: the undocumented parameter choice.
Most bioinformatics tools expose dozens of tunable parameters, and the defaults embedded in any given version represent one team's judgment about reasonable starting conditions — not universal scientific consensus. When researchers adjust these parameters during exploratory analysis, as virtually all do, the obligation to report final values in a methods section is rarely enforced with rigor. Reviewers, often lacking the computational background to scrutinize pipeline configurations in detail, may not flag the omission. The resulting publication describes a method that is nominally reproducible but practically opaque.
A high-profile illustration of this dynamic emerged from attempts to reproduce findings in single-cell RNA sequencing studies. Independent groups attempting to replicate published cell-type classifications from the same raw data found that choices about clustering resolution, dimensionality reduction parameters, and quality-control thresholds — none of which were fully specified in the original manuscripts — produced cell-type maps that diverged substantially from those reported. The underlying data were identical; the results were not.
Case Studies in Computational Irreproducibility
The genomics literature contains several well-documented cases that illuminate the scope of the problem. In 2015, a group of researchers at the University of Washington systematically attempted to reproduce eighteen published fMRI studies using the original data and described methods. Fewer than half yielded results consistent with the original claims — a finding that prompted significant reflection within the neuroimaging community and accelerated the adoption of containerized workflow standards.
More recently, efforts to reproduce machine learning classifiers trained on cancer genomic data have revealed a related challenge: when training and test data splits are not precisely recorded and archived, no subsequent researcher can reconstruct the exact model evaluated in the original paper. Given that minor differences in data partitioning can shift reported accuracy metrics by several percentage points, the clinical significance attributed to such models may rest on an unstable foundation.
These are not cases of fraud or negligence. They are cases of methodological documentation failing to keep pace with methodological complexity.
Toward a Standard of Computational Transparency
The research community has begun responding, though unevenly. Initiatives such as the NIH's Data Management and Sharing Policy, implemented in January 2023, establish baseline expectations for data archiving, but they do not comprehensively address the documentation of computational environments. More targeted proposals have emerged from within the bioinformatics community itself.
Workflow management systems — Snakemake, Nextflow, and the Common Workflow Language among them — offer one structural solution. By encoding entire analytical pipelines in executable, version-controlled formats, these tools allow a subsequent researcher to reproduce not merely the described method but the actual computational process. When combined with container technologies such as Docker or Singularity, which encapsulate the full software environment including operating system libraries, the result is a pipeline that can be re-executed on different hardware with substantially reduced environmental variability.
Journal-level policy changes represent a complementary mechanism. A growing number of publications, including Genome Biology and eLife, have introduced requirements for code availability as a condition of acceptance. Stricter implementations would mandate not merely that code be deposited but that it be independently executed by a reviewer or editorial staff member prior to publication — a standard sometimes called executable peer review.
Funding agencies carry particular leverage. Requiring that computational grant applications include explicit data management and pipeline reproducibility plans, and evaluating those plans as substantive scientific content rather than administrative formality, would create upstream incentives for more rigorous documentation practices.
Rethinking What Rigor Means in Silico
The deeper issue underlying all of these technical remedies is epistemological. The scientific community has not yet fully internalized the idea that a computational pipeline is itself a scientific instrument — one that requires the same careful characterization, calibration, and documentation as a mass spectrometer or a flow cytometer. The assumption that code, once written, speaks for itself has permitted a culture of methodological underspecification to persist in the computational sciences.
Addressing the reproducibility crisis in computational biology is not primarily a technical problem. It is a problem of professional norms, incentive structures, and the standards that journals, funding agencies, and academic institutions choose to enforce. The algorithms themselves may be sound. What is often missing is the disciplined transparency required to let others find out.